



The context-switch tax
If you juggle multiple projects across different clients, stacks, and architectures, you know the tax.
You switch from the billing API to the notification service and spend 20 minutes re-reading code just to remember how it's wired together. You onboard onto a new client's codebase and the architecture lives in someone's head, or in a Confluence page last touched in 2022. You open a new Claude Code session and your AI pair programmer starts from zero, re-discovering the same project structure you explained yesterday.

I hit this wall every week. Eleven engineers on my team at Insly, consulting work on the side, open source projects in my evenings. Every context switch meant either paying the cognitive tax myself or paying it in tokens while the model re-read everything from the top.
Karpathy's "LLM Wiki" idea
A while back, Andrej Karpathy posted a short pattern: instead of letting project knowledge live only in a single session's context, have the LLM maintain a persistent wiki in plain markdown. Scan the project, generate docs, refine over time, feed it back as context when you need it.
Beautiful idea. I sat down, connected the dots with the tools I use every day, and built out a full implementation.
That's llmwiki.
What it does
One command:
llmwiki ingest ~/workspace/my-api
```
{% endraw %}
The output is a structured markdown file with:
- **Domain and architecture** — what the project does, key design decisions
- **Service map** — every microservice with its purpose, stack, and responsibilities
- **Mermaid diagrams** — system architecture and ERDs, rendered natively in GitHub and Obsidian
- **API docs** — extracted from OpenAPI specs
- **Integration map** — databases, queues, external APIs with protocols and auth methods
- **Configuration reference** — env vars, feature flags, runtime modes
- **Auto-generated tags** in YAML front matter ({% raw %}`go, grpc, event-driven, kubernetes`{% endraw %})
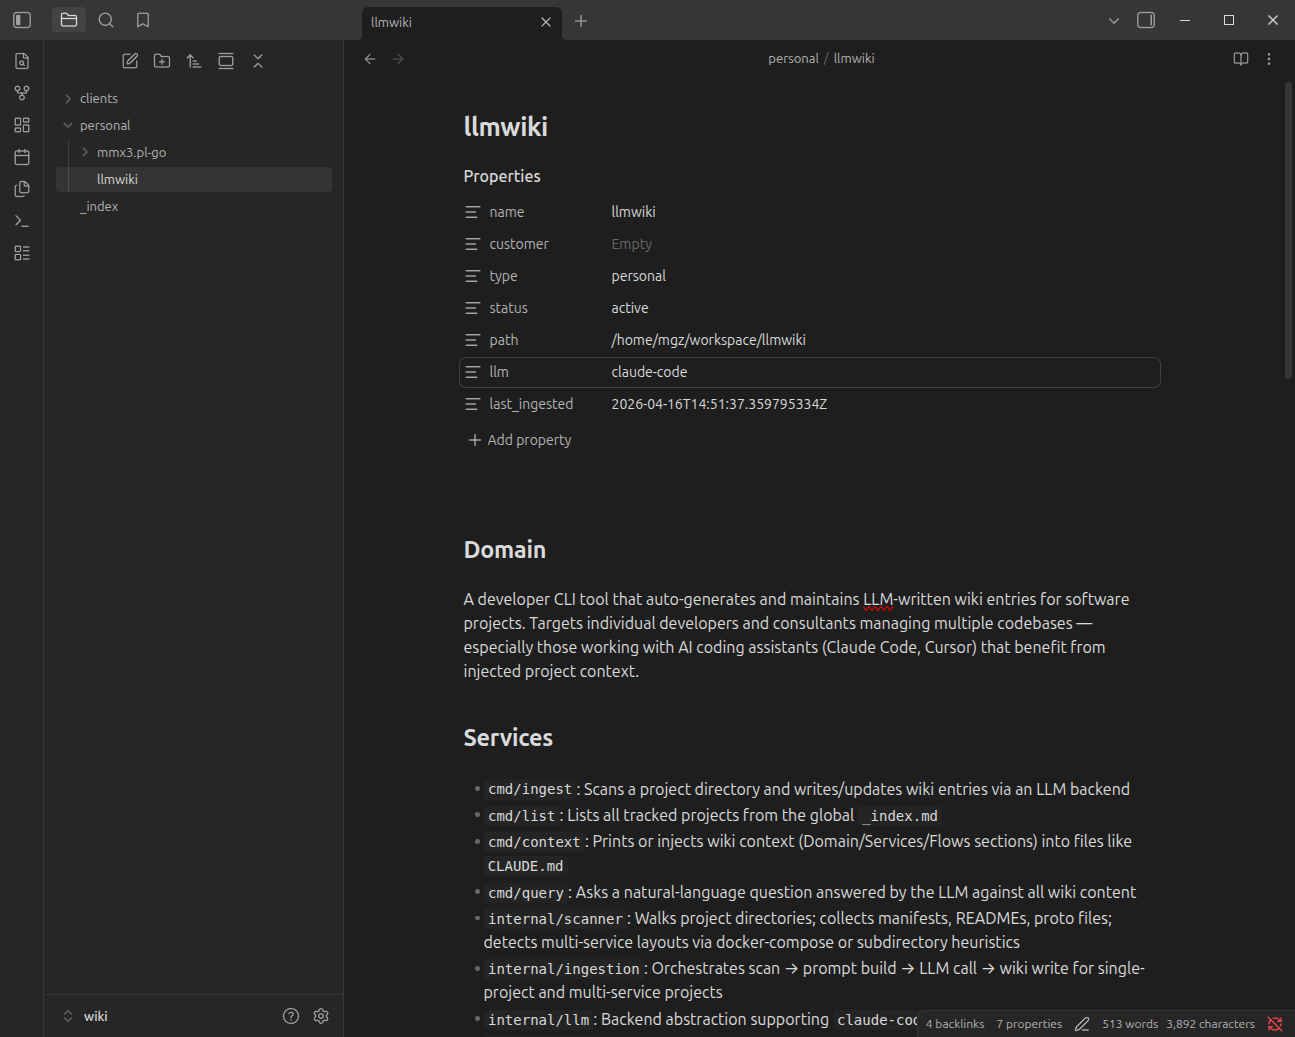
For clients with multiple projects, a separate command generates executive summaries with C4 system landscape diagrams. Mention a service name in any wiki entry and it becomes a clickable cross-reference to that service's page.
Re-running {% raw %}`ingest` doesn't regenerate from scratch. The LLM sees the previous entry and refines it. Knowledge compounds with every pass.
## The integrations that make it actually useful
This is where I moved past the original sketch and built out what works in my daily flow.
### Claude Code plugin
After {% raw %}`llmwiki hook install`{% endraw %}, a Stop hook fires at the end of every qualifying session. It reads the transcript, extracts the model's analytical responses, and pipes them to `llmwiki absorb`, storing the insight in persistent memory with zero extra action from me.
Later, I run:
```bash
llmwiki materialize my-project
```
This rebuilds the wiki from accumulated facts, costing ~5-15K tokens vs ~50-100K for a full ingest. Opus 4.7 is not cheap, and the difference shows up on the invoice fast.
### Graymatter memory layer
[Graymatter](https://github.com/angelnicolasc/graymatter) handles the persistent memory. Facts are stored per-project and per-customer, with semantic search using whatever embeddings you have available (Ollama → OpenAI → Anthropic → keyword-only fallback). A 30-day half-life means stale facts decay naturally. Cross-project patterns surface automatically on subsequent runs.
### NanoClaw Discord bot
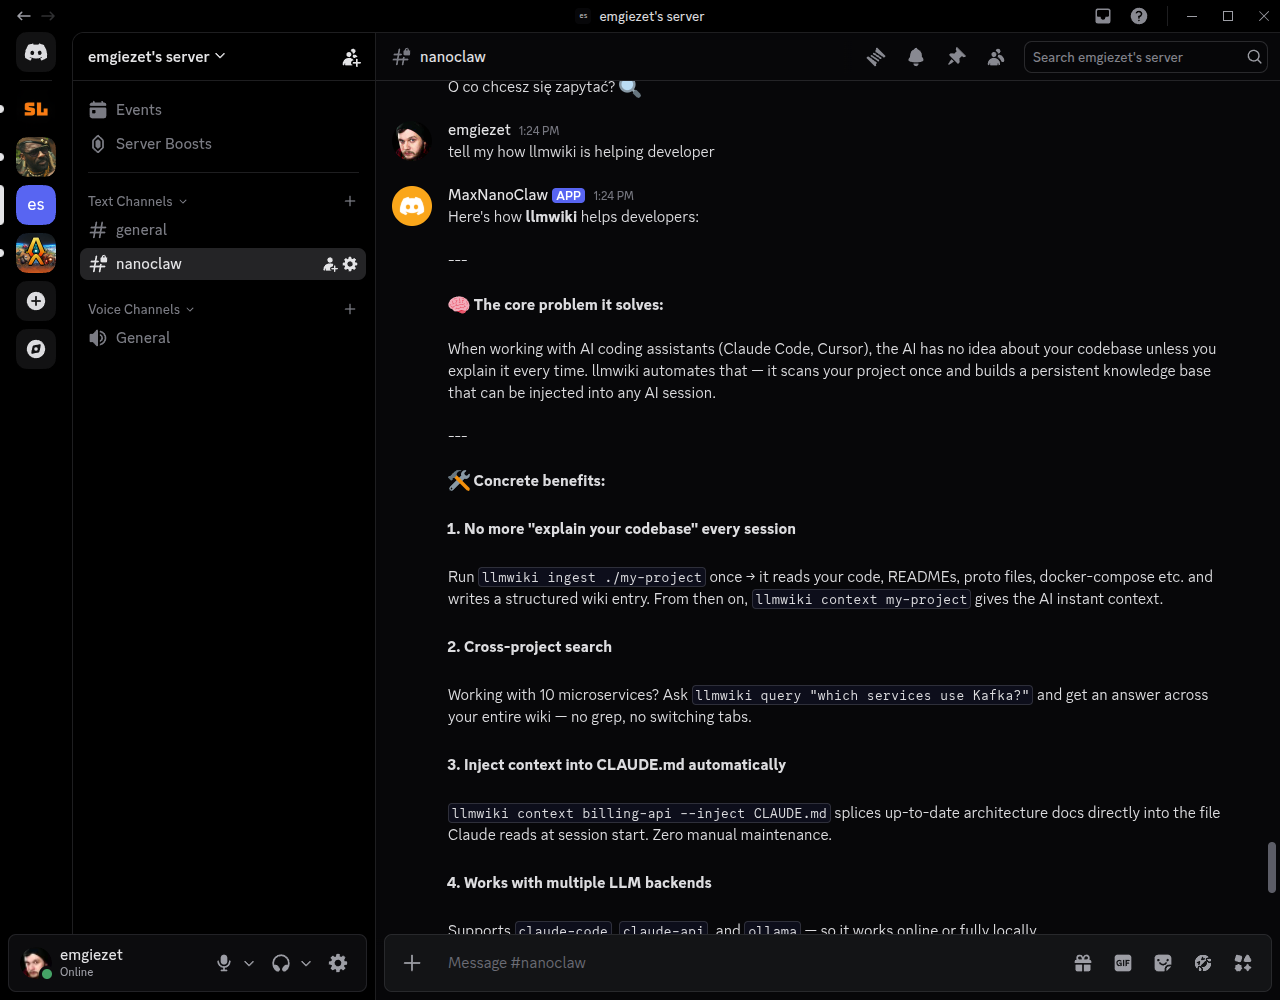
[NanoClaw](https://nanoclaw.com) is a Discord bot that queries your wiki and answers project questions directly in a channel. Useful when a teammate asks "how does the payment service talk to billing again" at 11pm and you don't want to dig through four repos to answer.
## Injecting context into AI sessions
The payoff is here:
{% raw %}
```bash
llmwiki context my-project --inject CLAUDE.md
```
{% endraw %}
This replaces a marker block in your {% raw %}`CLAUDE.md`{% endraw %}:
{% raw %}
```markdown
<!-- llmwiki:start -->
... domain, architecture, services, flows ...
<!-- llmwiki:end -->
```
{% endraw %}
Your AI assistant now starts every session with the full project map already in context. No more "can you look at the codebase and figure out what this does." No more paying the re-explanation tax.
## Who this is for
This is a tool for tech leads who keep 5-10 services in their head and onboard a new junior every other quarter. For consultants juggling clients where each one has a different stack and tribal knowledge living in Slack threads. For anyone working with AI coding assistants across multiple projects daily who wants to move their developer experience from "explaining the architecture again" to "the AI knows as much about this project as I do."
## Design choices worth calling out
- **Plain markdown with YAML front matter.** No proprietary format.
- **No database, no SaaS.** The wiki lives in {% raw %}`~/llmwiki/wiki/`{% endraw %} and syncs with git.
- **Obsidian vault out of the box.** Point Obsidian at the directory and get graph view plus clickable cross-links for free.
- **Ollama backend available** for NDA code and air-gapped environments. Client code doesn't have to leave the machine.
- **Baseline security audit before 1.0.** Path-traversal rejection, fenced LLM prompt pipeline, loopback-only Ollama default, symlink-TOCTOU handling. Full threat model in SECURITY.md.
## Install
```bash
curl -fsSL https://raw.githubusercontent.com/emgiezet/llmwiki/main/install.sh | sh
```
Binaries for macOS (arm64, amd64) and Linux (amd64, arm64). `go install github.com/emgiezet/llmwiki@latest` works too.
## v1.0.0 just shipped
Written in Go, MIT licensed, 72 commits to get here.
**Repo:** https://github.com/emgiezet/llmwiki
If you try it, I'd love to hear what worked and what didn't. Issues, feedback, PRs all welcome.