





At a glance
- Challenges a core assumption in robotics AI: Our research shows that running physical AI inference exclusively on onboard GPUs can limit robot performance, battery life, and scalability, and that offloading inference to edge or cloud GPUs can offer significant advantages.
- Demonstrates measurable benefits of inference offloading: Across representative mobile manipulation workloads, offloading improved task success rates, enabled larger AI models, and helped robots respond more effectively in dynamic, real-world environments.
- Extends robot operating time: Replacing power-hungry onboard AI compute with lightweight onboard hardware and remote inference can substantially improve battery life, enabling robots to operate longer between charges.
- Introduces a new capability in the Physical AI Toolchain: Developers can now containerize, deploy, and orchestrate robotics AI workloads across robots, edge infrastructure, and the cloud using Kubernetes-based tooling for distributed inference.
Readily-available physical AI, with robotics assisting users in manufacturing, home, and warehouses scenarios, holds immense potential to improve safety, productivity, and assistance across a wide range of tasks. In many ways, AI for the physical world represents a major frontier for AI . Physical AI must operate in open, unpredictable environments, interact with both other robots and people, and work with a diversity of embodiments. Realizing this vision requires advances along three dimensions: robot hardware, embodied AI models, and systems infrastructure for training and inference. While robot hardware and the AI models have advanced rapidly in recent years, we turn our focus on a relatively under-addressed aspect: inference infrastructure of physical AI. Enabling robots to effectively and safely operate in the physical world will require sophisticated systems to handle large volumes of distributed inference compute.
Today, the prevailing approach to physical AI is to provision a GPU onboard the robot, e.g., by wiring a GPU to the robot. In this model, the robot’s inference will be confined to the onboard GPU, and provide the robot with the necessary chunks and sequence of actions for the execution of its tasks. While higher-level planning may be performed in the cloud, task execution typically remains tied to the robot itself. We challenge this assumption. As physical AI models grow in size and sophistication, the constraints of onboard compute become increasingly apparent. GPUs consume significant power, reduce battery life, add cost and weight, and can limit the ability to run the latest generation of AI models.
To better understand the systems implications of physical AI, we conducted the first systematic study of robotics workloads. We focused on mobile robotic manipulation, with the canonical task such as “check for rubbish in the kitchen and put it in the trash.” Such a task involves planning the path to the kitchen, perceiving the environment to find rubbish, navigating to the rubbish, picking up the rubbish, and navigating back to the trash can for disposal. We evaluated representative models across three core capabilities: semantic mapping and planning, navigation, and manipulation, as summarized in Figure 2.

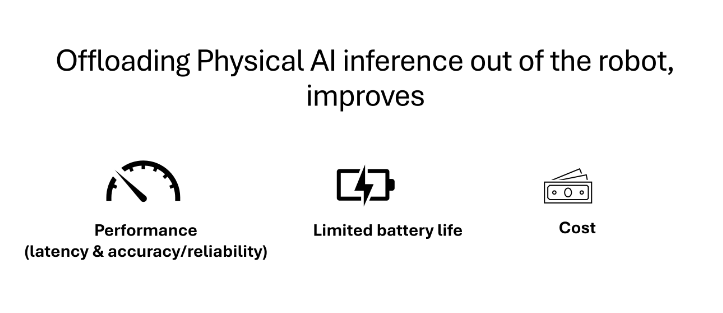
Offloading physical AI inference out of the robot improved its response time and accuracy, along with battery lifetime and cost. We evaluated the inference models across a range of onboard, edge, and cloud compute configurations. Details of the specific test hardware are available in our technical report.
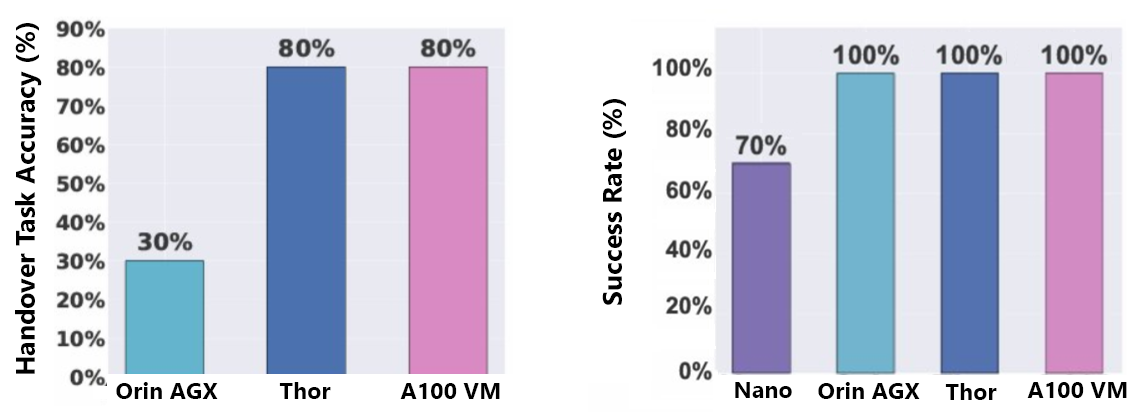
Benefits in task performance: Our evaluation shows offloading inference can significantly improve robot performance across mapping, planning, navigation, and manipulation workloads. Some smaller GPUs could not accommodate the mobile manipulation stack. On GPUs with sufficient memory, mapping and planning slowed by up to 383% compared to an A100, thus limiting the robot’s abilities in dynamic spaces. Navigation showed a 30% drop in its timely detection of obstacles with lighter GPUs. While the VLA models did not dramatically slow down with smaller GPUs, the slowdown was still sufficient to drop their accuracies by 50%. In other words, onboard GPUs limited the performance of the robots while offloading their inference to an on-premise or cloud GPU boosts their operations, as shown in the videos below and quantified in the graphs. As physical AI models continue to grow in size and complexity, the benefits of offloading are likely to become even more pronounced.
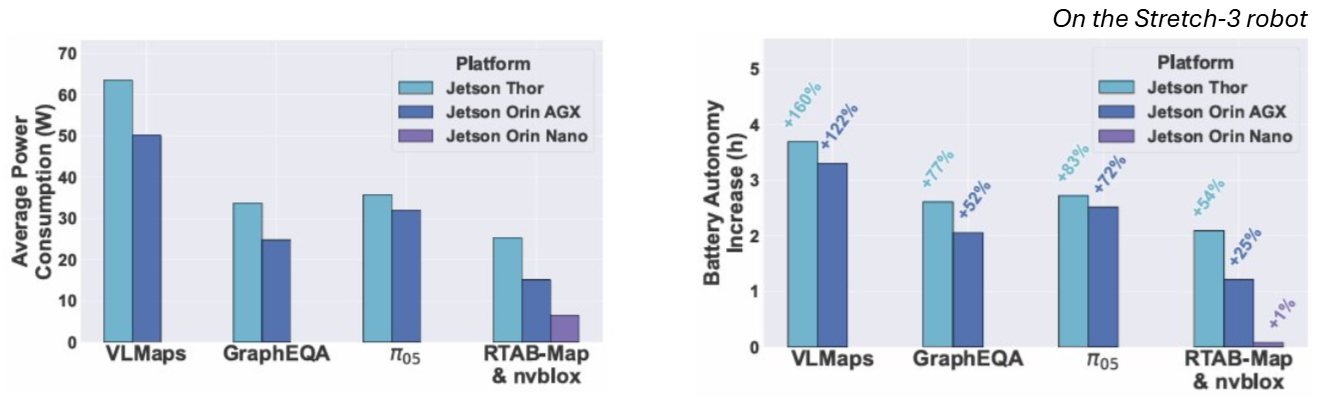
Benefits in battery lifetime: Beyond performance, onboard GPUs also significantly drained the battery life of the robot. We compared the increase in battery lifetime by replacing an onboard GPU with a Raspberry Pi-5 board and shipping all the data to the offloaded GPU. The larger onboard GPUs, such as Jetson Thor, drained robot batteries by up to 160% (or a few hours) for even the larger robots.
The above results show that offloading GPU inference out of the robot is critical for functioning in the open world with large models and long battery lifetimes. Nonetheless, offloading inference out of the robot involves a complex tradeoff involving performance, network latency and bandwidth, and available GPU resources. We believe that our measurement study will inform the design of physical AI inference systems.
PODCAST SERIES

AI Testing and Evaluation: Learnings from Science and Industry
Discover how Microsoft is learning from other domains to advance evaluation and testing as a pillar of AI governance.
Toolset for automatic offload
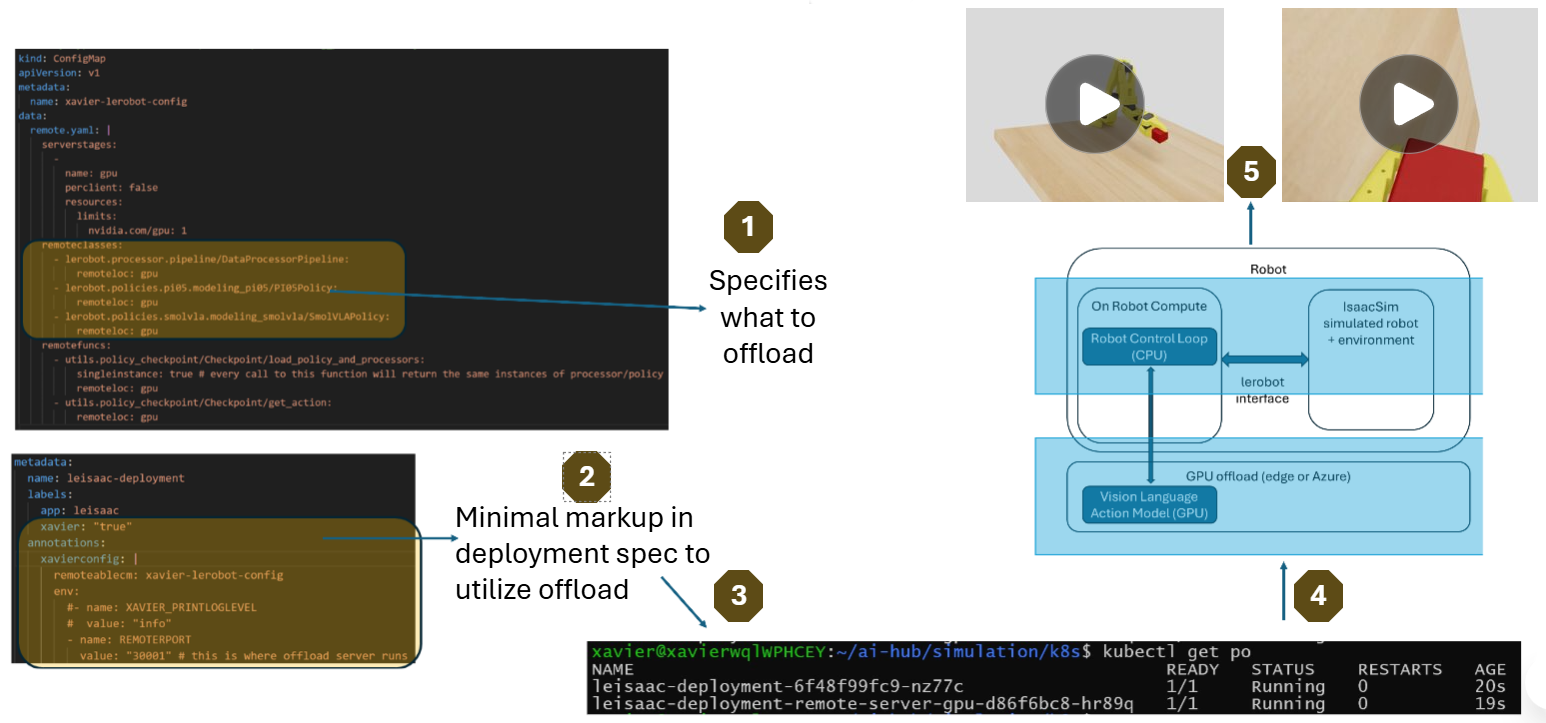
We have built a toolset for easy inference offloading out of the robot and distributing inference between the edge GPU and cloud. Kubernetes is a natural platform to provide a uniform abstraction to distribute robotic AI between the robot’s compute, edge GPU, and overflowing to the cloud. The toolset allows automatic containerization and offloading of robotics workloads using declarative specifications, distributes physical AI containers with smart policies using Kubernetes, and integrates with robotic simulators, LeRobot, and ROS2 for easy development. The sequence of steps below shows how the toolset can be prompted with what to offload, and how it creates a separate container for GPU inference and offloads the same.
Microsoft has recently released the Physical AI Toolchain (opens in new tab) for operationalizing physical intelligence at scale. Physical AI Toolchain is an open-source, production-ready framework that integrates Microsoft Azure (opens in new tab) cloud services with NVIDIA’s (opens in new tab) physical AI stack, accelerating robotics and physical AI developers to automate and scale data curation, augmentation, and evaluation across perception, mobility, imitation learning, and reinforcement learning pipelines. We are announcing the addition of an industry-first capability for offloaded physical AI inference for robots as part of the Physical AI Toolchain. This release includes example projects for offloading inference of a SO-101 and a UR10e. The videos below show the offloading of the inference of Microsoft’s Rho model, targeted at dual-arm robots, to a Jetson Thor GPU, which controls the actions of the Mobile Aloha robot (opens in new tab).
Check out the inference offload feature, look into the source code, and let us know your feedback. We have already tested it with many real-world use cases, and look forward to hearing about your deployment experiences.
The post Offloaded inference for real-world physical AI robotics appeared first on Microsoft Research.
SOCIAL SHARE CARD GENERATOR