
https://arena.ai
This Week in the Arena: Claude Sonnet 5.5, GPT-6.1 Sol, Gemini 4 Argon, and the latest AI rankings.
Follow Arena on X:
https://x.com/arena
NEWS: September 25–October 2, 2026
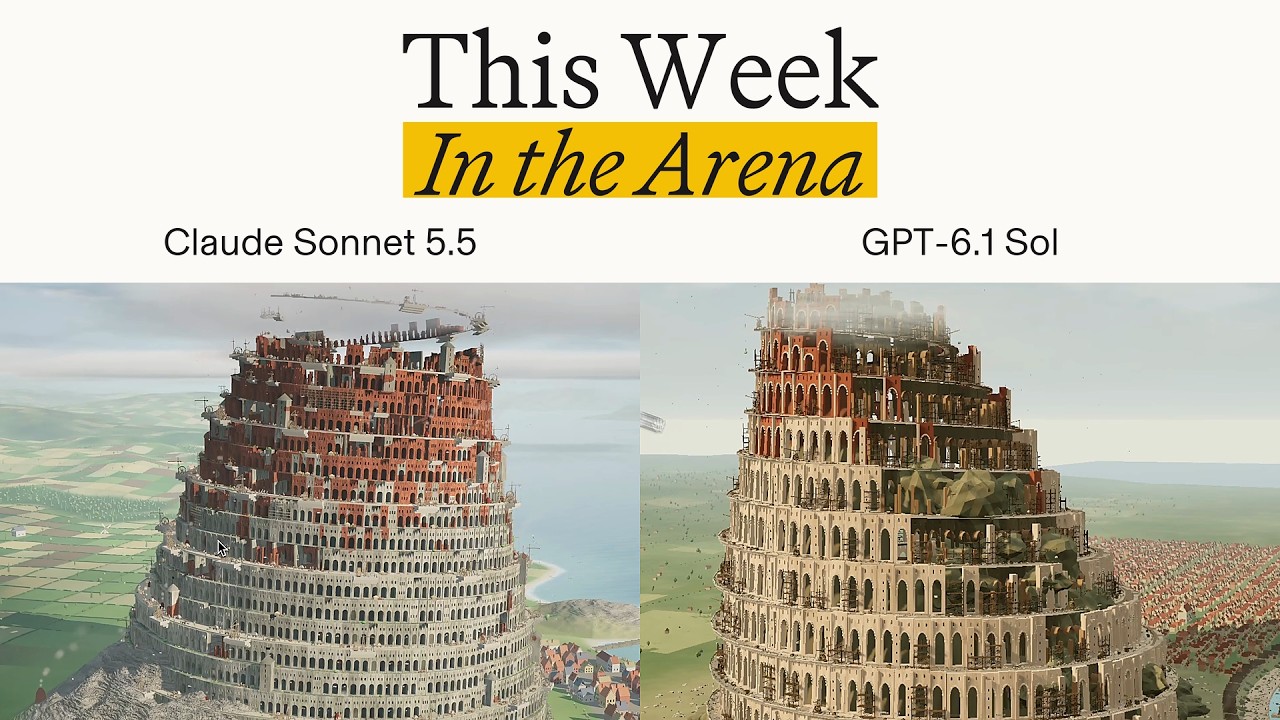
• Claude Sonnet 5.5 vs GPT-6.1 Sol: original Tower of Babel demos from Arena’s first impressions.
• Claude Opus 5.5 (High): #2 in Agent Arena, +12.15% net improvement at $1.31 median cost per task; 40–56% lower cost than Opus 5 (High/Max).
• Gemini 4 Argon (High): #1 in Text Arena with 1525 points at its September 30 announcement.
• MiMo-V2.6-Pro: #5 among open-source models in Agent Arena, with +3.17% net improvement across 8.1K+ sessions.
• RIP em dashes: Claude Opus 5.5 uses 95% fewer em dashes than Opus 5 in Arena’s high-reasoning Text Arena sample (0.8 vs 15.2 per 1,000 words).
• One prompt, 19 takes on Ancient Rome: Arena’s model progression, featuring Claude Opus 5.5 and Claude Sonnet 5.5 demos.
• AI judge self-bias: across 12 models, judges chose their own answers 58% of the time on average; people chose those same answers 34% of the time.
• Steerability: Arena’s updated methodology now credits getting it right the first time and evaluates every judgeable assistant turn.
#ArenaAI #AI #TechNews